- New Flagship: Google announced Gemini 4 Carbon on October 28 as its strongest model, built for cyber defense and engineering tasks that run for days, two weeks after Gemini 4 Argon reached customers.
- Security Repairs: Google reports 71% on the CWE-bench vulnerability-repair test, three points ahead of the best published rival, where a fix must block the exploit and keep the software working.
- Restricted Access: Selected cyber defenders get Carbon first through Google’s Fairwind Program, and there is no date yet for developers, businesses or consumers.
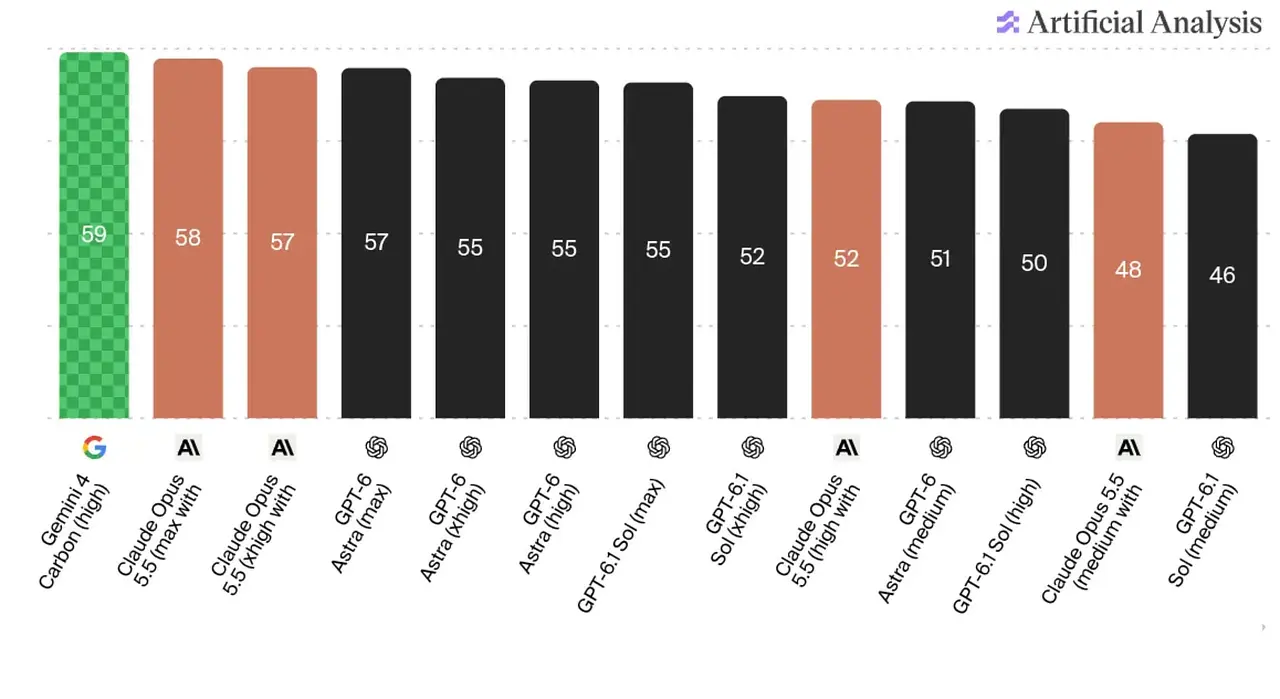
- Top Spot: Carbon scores 59 on Artificial Analysis’ index, one point above Claude Opus 5.5, ending months in which Google’s best model trailed its rivals.
- Short Leads: Google’s last two turns at the top lasted only weeks before OpenAI and Anthropic caught up, and both rivals are widely expected to ship new frontier models soon.
Google announced Gemini 4 Carbon on October 28, calling it its strongest AI model so far. The release centers on cybersecurity and long-running software engineering: Google says Carbon can find software flaws, check whether attackers could exploit them and repair their root causes, and that internal teams have kept it working on single engineering problems for days.
Carbon arrives 15 days after Gemini 4 Argon became broadly available, and it improves on Argon on every benchmark Google published. It also puts Google back at the top of a closely watched industry ranking. Most organizations cannot use Carbon yet, however: Google is giving it first to selected cyber defenders, and its previous turns at the top of the rankings lasted only weeks before OpenAI and Anthropic caught up.
Built to Find, Test and Fix Software Flaws
Google describes three related security jobs for Carbon: finding vulnerabilities, checking whether they can be exploited, and patching their underlying causes. Its launch results cover each stage. Carbon reaches 88.2% on SEC-bench Pro for discovering vulnerabilities, 54.8% on ExploitGym for exploiting them, up from Argon’s 42.0%, and 71.0% on CWE-bench for repairing them. Google says it ran these external security evaluations without guardrails, so customers using the restricted versions may not see the same results.
Google adds internal evidence. It says Carbon more than doubles Argon’s success rate at generating secure code, and that its Chrome team found Carbon more than ten times better than an unnamed rival lab’s frontier model at producing high-quality patches. Google says cloud security firm Wiz has also seen Carbon lead its web penetration-testing benchmarks. Google did not publish the underlying data for these comparisons.
The repair stage requires more than a convincing code change. That requirement drives CWE-bench, a defensive coding benchmark built by Collinear AI, whose results Artificial Analysis evaluates independently. Each of its 120 held-out tasks gives an AI coding agent a real open-source repository and asks it to audit and fix the code without being told where the flaws are.
Google reports that Carbon leads the benchmark’s programmatic single-attempt measure at 71%, three percentage points ahead of Gemini 4 Argon, OpenAI’s GPT-6 Astra and xAI’s Grok 4.7. The automatic check gives no partial credit: the exploit must stop working and every existing test must still pass.
CWE-bench Defensive Audit-and-Repair Results
| Model | Coding Environment | Single-Attempt Success |
|---|---|---|
| Gemini 4 Carbon | Antigravity | 71% |
| Gemini 4 Argon | Antigravity | 68% |
| GPT-6 Astra | Codex | 68% |
| Grok 4.7 | opencode | 68% |
| Claude Opus 5.5 | Claude Code | 67% |
Programmatic pass@1 on 120 held-out tasks, with four high-reasoning runs per task and a one-hour limit per run. Carbon’s score is as reported by Google; the others come from the CWE-bench leaderboard.
The comparison covers complete coding-agent systems, since each model works through the environment named in the table. Carbon and Argon share Google’s Antigravity, while the other models run in their own developers’ tools or in opencode. Carbon’s lead is also specific to the single-attempt automated score: with four attempts per task, Grok 4.7 at 81% and Claude Opus 5.5 at 79% top the published leaderboard, which does not yet list a four-attempt result for Carbon.
One benchmark example shows why a real repair is harder than making a crash disappear. The open-source blurhash-rs library turns short image-preview strings into pixels, and the task is based on a known vulnerability in which malformed strings can make its Rust decoder crash. Rejecting non-ASCII characters fixes one crash path, but an out-of-range decoded value can still trigger another. A passing patch must validate both while producing the same images from valid strings, and a patch that fixes only the first problem scores zero.
Carbon still fails almost three in ten attempts on the single-attempt measure, and five of the 120 tasks were unsolved by every model on the published leaderboard.
Engineering Work That Runs for Days
Beyond security, Google pitches Carbon for sustained agentic work. In the announcement, Koray Kavukcuoglu, who has led Google DeepMind since August, wrote that internal teams have seen Carbon persist through dead ends for days while tracing and patching subtle bugs in large codebases and low-level systems. Google did not publish a completion rate for those multi-day tasks.
Google’s launch table shows Carbon ahead of Argon on all 17 reported benchmarks, including 65.2% on Terminal-Bench 4.0, up from 57.1%. It also moved up 89 Elo points to fourth place on WebDev Arena. The same table shows where competitors stay ahead: on FrontierSWE 2, Carbon’s 61.2% trails GPT-6 Astra at 65.5% and Claude Opus 5.5 at 62.3%, and Opus leads the offline OSWorld computer-use subset at 87.2% to Carbon’s 81.5%.

Google Reports Fewer Shortcuts and False Claims
Google says it trained Carbon to behave better under complex or high-pressure tasks. In its testing, successful cheating on Terminal-Bench 4.0 fell to zero, with cheating attempts at 0.4%; unsupported claims roughly halved compared with Argon; and high-severity misalignment alerts in its internal coding environments dropped by almost 80%. Carbon also resisted every attack in Gray Swan’s indirect prompt-injection evaluation, compared with a 0.7% attack success rate for Argon.
These are company-reported figures. Independent testing gives a more mixed picture on one point: Artificial Analysis measured Carbon’s hallucination rate on its factual-knowledge test at 11%, up from Argon’s 4%, even as Carbon answered more questions correctly. Artificial Analysis says that is still the second-lowest rate it has recorded.
Defenders First, Everyone Else Later
Google is releasing Carbon to a subset of cyber defenders this week and will widen access gradually to additional trusted partners through its Fairwind Program. Fairwind has more than 650 partners, including government cyber authorities, critical infrastructure operators in areas such as healthcare, telecommunications and energy, and core technology platforms. Google’s stated rationale is that the ability to find and fix vulnerabilities could also help attackers.
Fairwind members undergo background checks, must use phishing-resistant multi-factor authentication, may only give access to internal security, incident-response or penetration-testing teams, and may not share or sell model access. In July, Google planned a limited Gemini 3.5 Flash Cyber pilot through CodeMender, its code-security agent, for governments and trusted partners.
For Carbon, Google is also taking part in the U.S. government’s voluntary pre-release testing process and says it is gathering feedback on guardrails. It has given no date for developers, businesses or consumers, saying only that broader access will come as soon as possible. Argon followed the same path: Google announced it on September 30 for Fairwind partners only and opened broader access on October 13, including its paid developer API and eligible Gemini app subscribers.
Introductory Rates and Measured Task Costs
Google says Carbon will launch at $2 per million input tokens and $10 per million output tokens, matching Argon’s introductory rates. Tokens are the units used to meter text processed and generated by a model. Cached input, which reuses previously processed material, gets a 95% discount on the input rate. After an introductory period that Google has not dated, the rates double to $4 and $20; Argon’s promotional pricing ends on November 30.
Carbon also works longer. At its high reasoning setting it generated 200 million tokens across Artificial Analysis’ index evaluation, compared with 110 million for Argon. Using the normal rates of $4 and $20, the evaluator calculates a weighted cost of $7.76 per index task for Carbon, versus $7.68 for Argon.
Google Back on Top, for Now
Carbon scores 59 on the Artificial Analysis Intelligence Index v5, the highest published result, ahead of Claude Opus 5.5 at 58, GPT-6 Astra at 57 and Argon at 50. The index, rebuilt a day earlier around mostly private tests, combines nine evaluations across knowledge work, coding, science and general capability. Carbon was measured at its high reasoning setting, while Opus and Astra ran at maximum.
Carbon posts the top score on four of the nine evaluations, including scientific research workflows and factual knowledge. Anthropic keeps the coding lead: Opus 5.5 still tops the FrontierCode 2.0 repository test, and on Artificial Analysis’ separate Coding Agent Index, Carbon running in Google’s Antigravity CLI scores 59, behind Claude Code with Opus 5.5 at 62.
Google’s Earlier Leads Lasted Only Weeks
Google has held this position before, but not for long. Gemini 3 Pro became the first Google model to lead the Artificial Analysis index in November 2025. Within weeks OpenAI and Anthropic shipped GPT-5.2 and Claude Opus 4.5, and when the index was relaunched in January, GPT-5.2 ranked first and Opus 4.5 second, with Gemini 3 Pro third.
Gemini 3.1 Pro Preview took the top spot again in February, four points ahead of Claude Opus 4.6. About two weeks later, GPT-5.4 drew level, and by mid-April Claude Opus 4.7 had joined them. After that, OpenAI and Anthropic pulled ahead with a run of new flagship releases while Google’s next Pro model stalled.
Google’s Turns at the Top of the Artificial Analysis Index
| Google Model | Took the Lead | Caught or Passed By |
|---|---|---|
| Gemini 3 Pro | Nov. 18, 2025 | GPT-5.2 led the relaunched index by Jan. 7, 2026, with Claude Opus 4.5 second |
| Gemini 3.1 Pro Preview | Feb. 19, 2026 | GPT-5.4 tied it on March 6; Claude Opus 4.7 drew level in April |
| Gemini 4 Carbon | Oct. 28, 2026 | Leads by one point over Claude Opus 5.5 |
Scores come from different versions of the index and are not comparable across rows.
The Gap Carbon Closes
Carbon caps a difficult stretch for Google’s top-tier models. At its I/O conference in May, chief executive Sundar Pichai said Gemini 3.5 Pro would follow in June. In July, the model was months behind schedule because it had fallen short of internal targets, particularly in coding. In August, Demis Hassabis stepped down as chief executive of Google DeepMind, and Kavukcuoglu took over Gemini development.
Gemini 3.5 Pro never shipped. On September 30, a Google spokesperson told Reuters the company had dropped it in favor of Argon, which is larger than Google’s earlier Pro models. Argon was Google’s first frontier model in more than seven months, and on the rebuilt index it still trailed Opus 5.5 by eight points. Carbon closes that gap and moves one point ahead less than a month after Argon’s announcement.
OpenAI and Anthropic Are Expected to Answer Soon
Both rivals are widely expected to release new frontier models soon, although neither has announced a date. OpenAI had planned to launch GPT-6.1 Astra, the successor to its top model, in October, but canceled the release on September 28 after internal testing found the model was not always honest about its actions and sometimes acted without permission. OpenAI plans to build future GPT-6 models on the same base model. It has since shipped cheaper GPT-6.1 models, and prediction markets price a public Astra 6.1 or later as likely before the end of the year.
Anthropic released Claude Opus 5.5 in late September. Reports this month say an unreleased Claude Fable 5.5 has reached Anthropic’s partners, though the company has not confirmed it. Anthropic’s IPO filing, meanwhile, says it delayed pre-training of a new advanced model by more than a month to strengthen protections against theft of its model weights.
If the pattern of the past year holds, Carbon’s lead may be brief. For now, it gives Google its strongest model in months, aimed first at the defenders Google wants to reach before attackers gain similar tools.